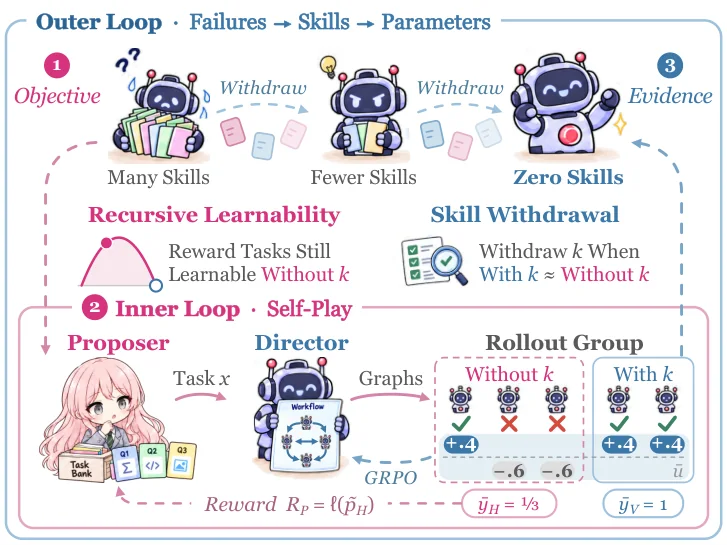
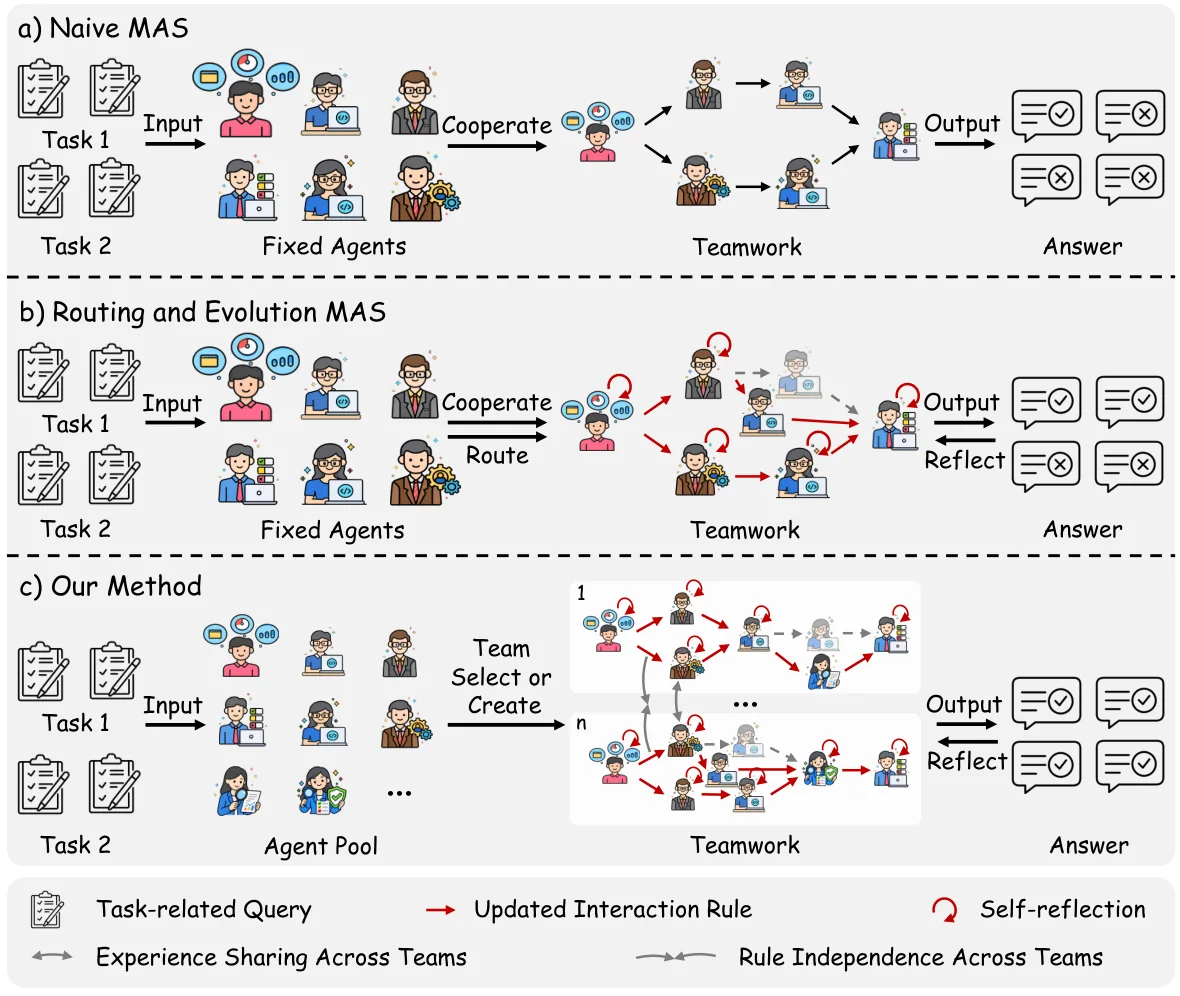
Large models have improved mostly through outside signal: human labels, curated benchmarks and curricula designed by people. Getting them to keep improving without that help is still an open problem. A system that does it has to set its own practice problems, grade its own answers, and decide what to learn next. Three recent preprints work on parts of this. A-RSI swaps out tasks that have stopped teaching anything and checks answers with programs. R²Orch uses self-play to choose training tasks for agent orchestrators. EvoTeam changes how teams of agents are organized based on experience. This piece explains what is still missing and what a real solution would need to show.
Research Digest » October 2026 research » The Unsolved Problem
The Unsolved Problem · October 2026
Self-improvement without labels: three papers try to build their own referees and curricula
Removing human labels means a system must pose its own problems, judge its own answers and decide what to learn next. Three new preprints each take on part of that job.
AI agentsMultimodal AI
Super Saver
Keep reading, and get the Explain it Like I'm 12 version
The full article and its Explain it Like I'm 12 version are for Super Saver members. Sign in if you're a member.
Your account doesn't include Super Saver yet. Upgrade to read every issue in full.
Figures from the research
More from October 2026
 Paper of the Month
 Breakthrough 1 of 5
 Breakthrough 2 of 5
Keep exploring this issue
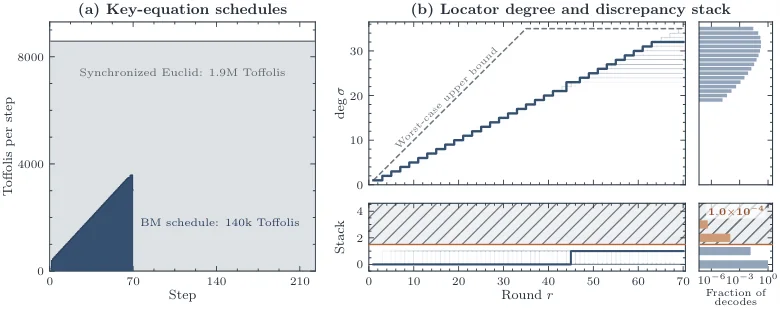
Paper of the MonthLLM-guided search finds cheaper quantum circuits in seven of eight benchmark tasks
A language model proposes circuit designs, a strict classical checker verifies and scores them, and the results beat prior designs while making a previously impractical classical algorithm usable in quantum form.
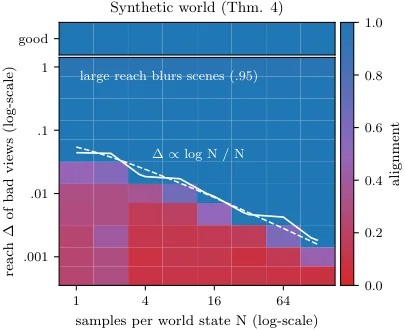
Breakthrough 1 of 5A theorem for the Platonic Representation Hypothesis points to positive pairs, not scale
Balestriero and LeCun prove when separately trained JEPAs learn matching representations, then show a 109M-parameter text model aligning with vision better than a 72B language model.
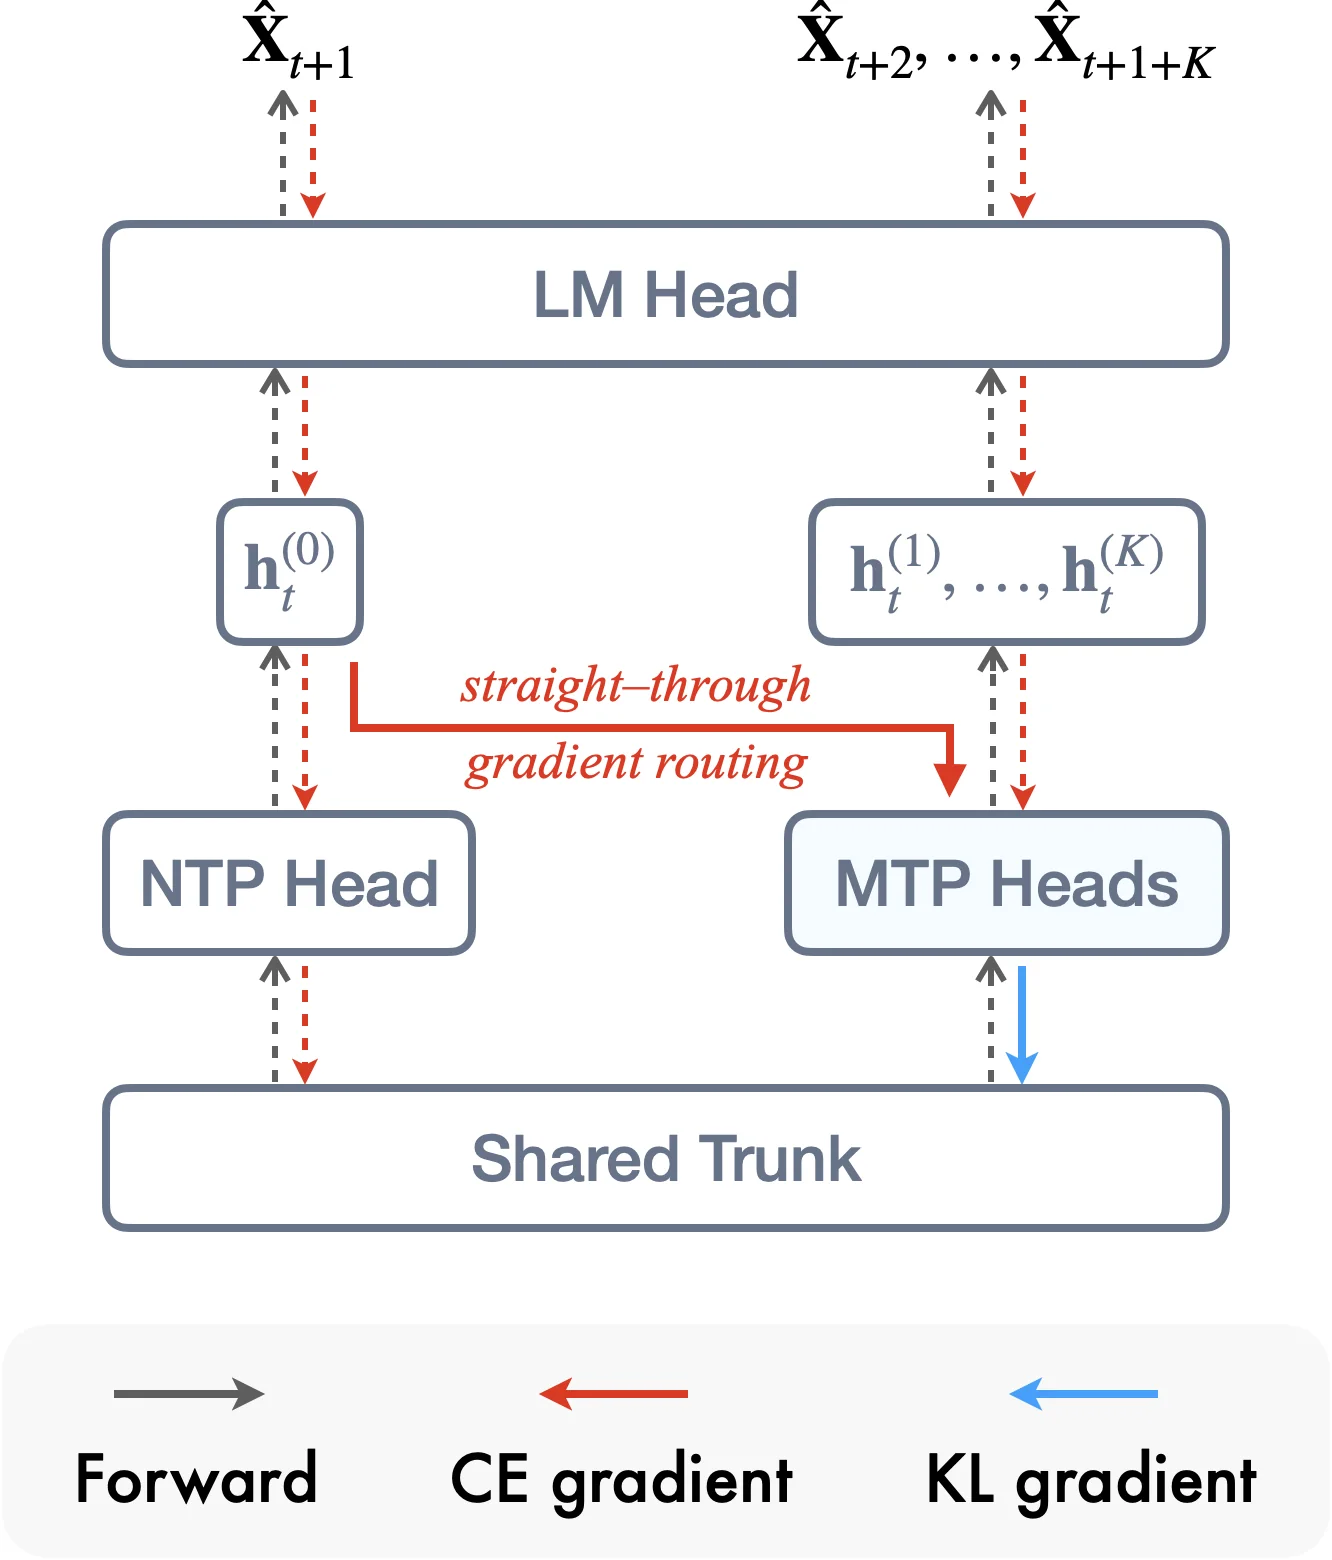
Breakthrough 2 of 5Soft-MTP: a one-line change strips noise out of multi-token prediction training
A new preprint finds that the standard way of training multi-token prediction heads hides a noisy gradient term. Removing it improved perplexity, speculative decoding and reasoning at no measurable extra cost.